Product feeds fail long before the campaign notices
A Shopping campaign can look healthy while the catalog beneath it is deteriorating.
A supplier changes identifiers.
An ERP delays inventory updates.
A spreadsheet rule removes a product category.
A title transformation corrupts a brand field.
A regional price changes but the landing page cache does not.
The advertising platform sees the final output.
It does not necessarily tell the media team where the data first went wrong.
That is why feed operations should be designed as a data stack.
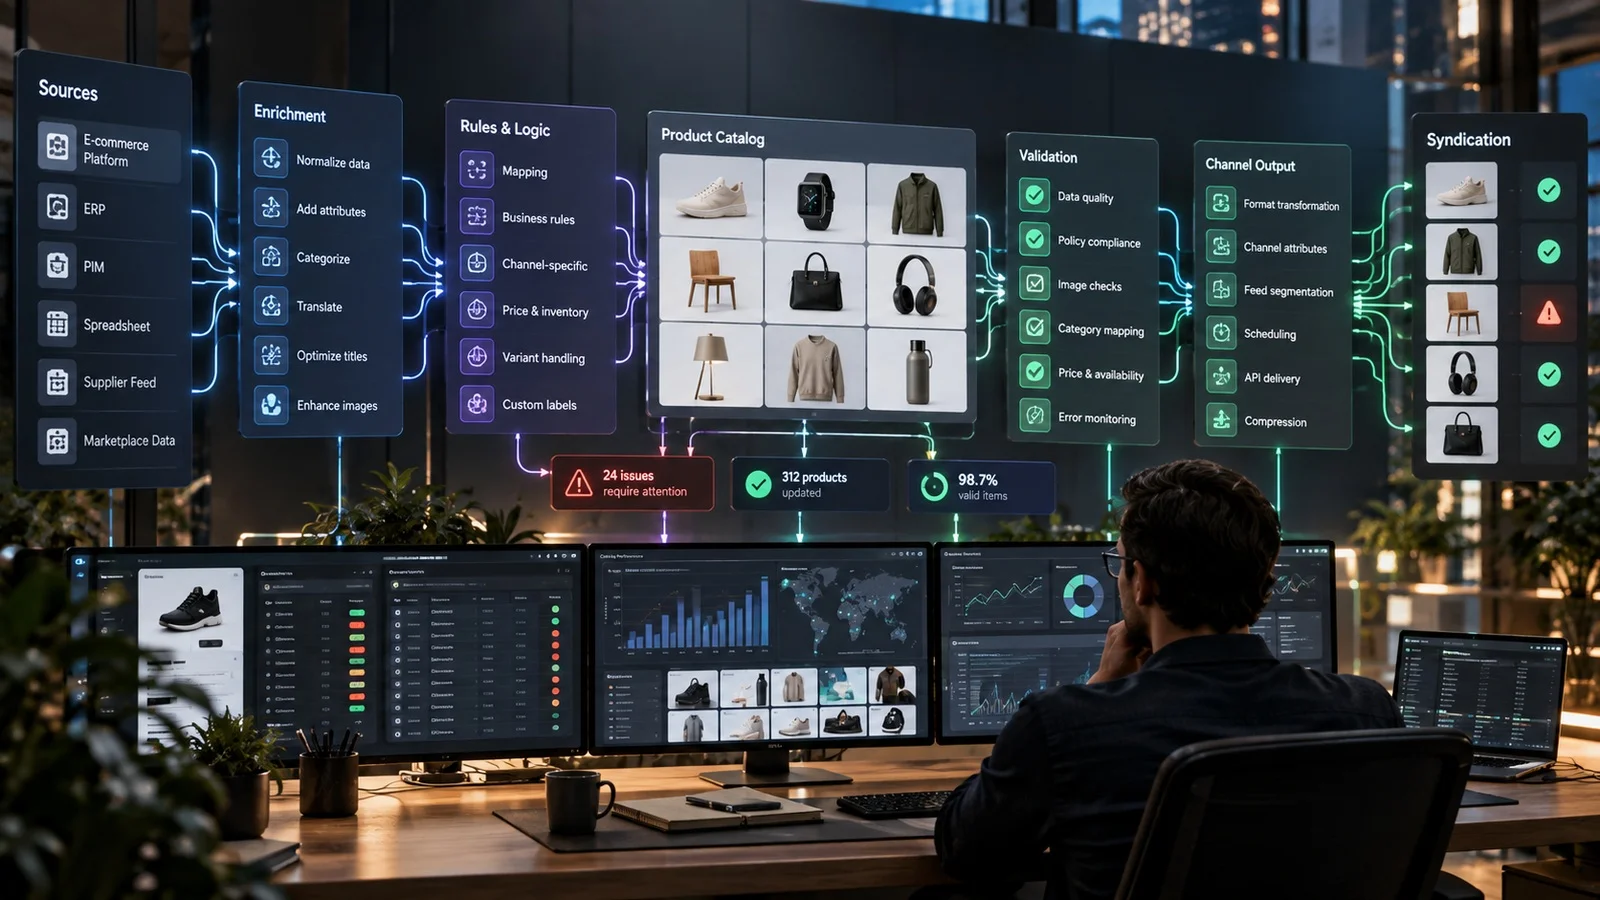
The system needs to make five jobs visible:
source → normalize → enrich → validate → syndicate
A tool that performs all five can still be useful.
The architecture should still distinguish them.
Layer 1: define the product source of truth
Before choosing a feed tool, decide where each attribute is authoritative.
Possible systems include:
- ecommerce platform;
- ERP;
- PIM;
- supplier database;
- inventory system;
- DAM;
- pricing engine;
- promotions system;
- finance or BI model.
This matters because feed platforms are excellent at transforming data and dangerous as accidental masters of data they do not own.
A marketing team may use a rule to rewrite titles.
It should not manually maintain core inventory if the ERP already owns it.
A retailer may enrich product type for advertising.
It should not invent a GTIN because the master catalog is incomplete.
The stack should know which fields can be transformed and which fields must be inherited.
Layer 2: normalize before optimizing
Catalogs accumulate inconsistency.
One source says `Black`.
Another says `BLK`.
A third says `black`.
One system uses centimeters.
Another uses millimeters.
One product family uses `Men > Shoes`.
Another uses `Menswear / Footwear`.
Feed tools such as Feedonomics and Channable are valuable partly because they can centralize transformation rules across large catalogs and multiple destinations.
Feedonomics describes its workflow around connecting source systems, standardizing data, optimizing attributes and syndicating to many destinations. Channable emphasizes rules, mapping and automated feed output.
Those are commercial platforms.
The underlying architecture is vendor-independent:
Normalize once before applying channel-specific logic.
If every destination independently fixes the same source inconsistency, the stack becomes difficult to maintain.
Layer 3: enrichment should add decision value
Feed enrichment can improve discoverability and campaign control.
Useful additions include:
- internal product taxonomy;
- margin band;
- lifecycle stage;
- season;
- stock depth;
- promotion eligibility;
- bestseller status;
- customer-rating band;
- strategic category;
- search-language improvements.
The important distinction is between descriptive enrichment and decision enrichment.
A better color description may improve listing quality.
A margin label may change where budget should be allowed to flow.
Both matter.
Only the second directly connects catalog data to media economics.
This is one reason custom labels remain powerful in Shopping operations: they let internal business logic become available to campaign structure and reporting.
Layer 4: channel transformations should be isolated
Google, Meta, TikTok, Amazon, Microsoft and retail-media networks do not use identical schemas.
A clean internal product object should therefore be transformed into channel-specific outputs.
Do not contaminate the source catalog with every destination's special requirement.
The stack should separate:
canonical product data from channel representation.
This makes changes easier to manage.
If Google changes a required field, the Google output can be adjusted without altering the core product model.
If a retailer adds a marketplace, the team builds a new transformation layer rather than reformatting the source system.
Layer 5: validation is a production control
Most teams validate only after a destination rejects products.
That is late.
Validation should happen before syndication where possible.
Useful checks include:
- required identifiers missing;
- duplicate item IDs;
- invalid price;
- negative inventory;
- unsupported characters;
- malformed URLs;
- inaccessible images;
- missing category mapping;
- title length;
- inconsistent variants;
- price-to-landing-page mismatch;
- expired promotion dates.
Some checks are destination-specific.
Others are business-specific.
A margin label with an impossible value may not trigger a Google error.
It can still damage budgeting logic.
This is why feed QA cannot be outsourced completely to Merchant Center diagnostics.
Channel acceptance and business correctness are different standards.
Layer 6: syndication needs monitoring
A successful export is not the same as successful syndication.
The team needs to know:
- when the feed last ran;
- how many products were exported;
- how many were accepted;
- how many were changed;
- whether critical categories disappeared;
- whether the destination acknowledged the update;
- whether the number of eligible products changed materially.
For large catalogs, monitor product counts over time.
If the approved catalog normally contains 120,000 products and drops to 72,000 overnight, the system should detect that before the morning performance report.
This is basic reliability engineering.
When Merchant Center is enough
Not every retailer needs Feedonomics, Channable or another enterprise feed platform.
Merchant Center itself supports multiple data sources, supplemental sources and the Merchant API. Google's Merchant API can manage primary, supplemental, inventory, promotion and review data sources programmatically.
A retailer with:
- one storefront;
- one main advertising destination;
- clean product data;
- limited transformation needs;
- modest catalog complexity;
may be better served by native Merchant Center plus a disciplined ecommerce integration.
Adding a feed platform introduces:
- another vendor;
- another transformation layer;
- another source of credentials;
- another place rules can conflict;
- another bill.
Tool sophistication should match catalog complexity.
When a dedicated feed platform becomes justified
A specialist platform becomes more valuable as the number of destinations and rules grows.
Typical triggers include:
- large SKU counts;
- many markets;
- many languages;
- several ad platforms;
- marketplaces and retail media;
- frequent attribute transformation;
- supplier feeds;
- complex promotions;
- agency-scale client portfolios;
- operational teams without engineering capacity for custom pipelines.
The justification should be expressed as reduced operational risk or reduced maintenance cost.
“More channels” alone is not enough.
The team should know which manual transformations, QA checks or engineering tasks the platform will replace.
Failure mode: the spreadsheet becomes production infrastructure
Spreadsheets are useful.
They are also one of the most common sources of feed fragility.
A supplemental sheet begins as a quick fix.
Then it contains custom labels.
Then title rules.
Then regional exclusions.
Then promotion logic.
Then a person who understands it leaves.
The spreadsheet is now a production application without:
- version control;
- typed fields;
- testing;
- permissions discipline;
- automated rollback;
- monitoring.
The correct response is not “never use spreadsheets.”
It is to identify when a temporary operational tool has become core infrastructure.
At that point, move stable logic into a managed system.
Failure mode: duplicated rules across layers
Suppose the ecommerce platform rewrites titles.
Then the feed platform rewrites them again.
Then Merchant Center applies another rule.
The final output may be correct today.
The next person cannot explain why.
A strong feed stack minimizes transformation depth.
Each rule should have one preferred layer.
As a principle:
- product truth belongs upstream;
- reusable normalization belongs near the canonical model;
- channel-specific mapping belongs in the channel transformation;
- emergency destination overrides should remain exceptional.
This makes debugging tractable.
Failure mode: optimizing rejected products instead of valuable products
Feed teams often celebrate approval rate.
Approval rate can be misleading.
If 99.5% of products are approved but the missing 0.5% contains the highest-margin product family, the commercial impact can be severe.
Prioritize issues by business value at risk.
A useful operational score can include:
- revenue share;
- margin share;
- strategic importance;
- inventory depth;
- promotion status;
- historical spend.
The feed queue should then address the products whose absence costs the business the most.
That is a better model than resolving warnings in the order a dashboard displays them.
Feed tooling is moving into AI discovery too
Feed platforms are expanding beyond traditional ad destinations.
Feedonomics now positions its catalog infrastructure across more than 2,000 destinations and explicitly includes AI discovery surfaces among them. Channable has also introduced AI-assisted attribute mapping for multichannel feed setup.
Those are vendor product claims.
They point to a broader shift.
Product data is becoming useful not only for Shopping campaigns but for marketplaces, retail media, recommendation systems and AI-mediated commerce.
That increases the value of a clean canonical product model.
A retailer that treats every channel as a separate export problem will accumulate more operational debt as the number of surfaces grows.
The tool is not the stack
Feedonomics, Channable, Merchant Center and custom APIs can all participate in a mature architecture.
None of them defines it.
The stack is the operating agreement that determines:
where product truth lives, where it is transformed, how it is validated, which system owns each rule and how failures are detected.
Once those boundaries are clear, tool selection becomes easier.
Without them, a more powerful feed platform simply automates a mess.