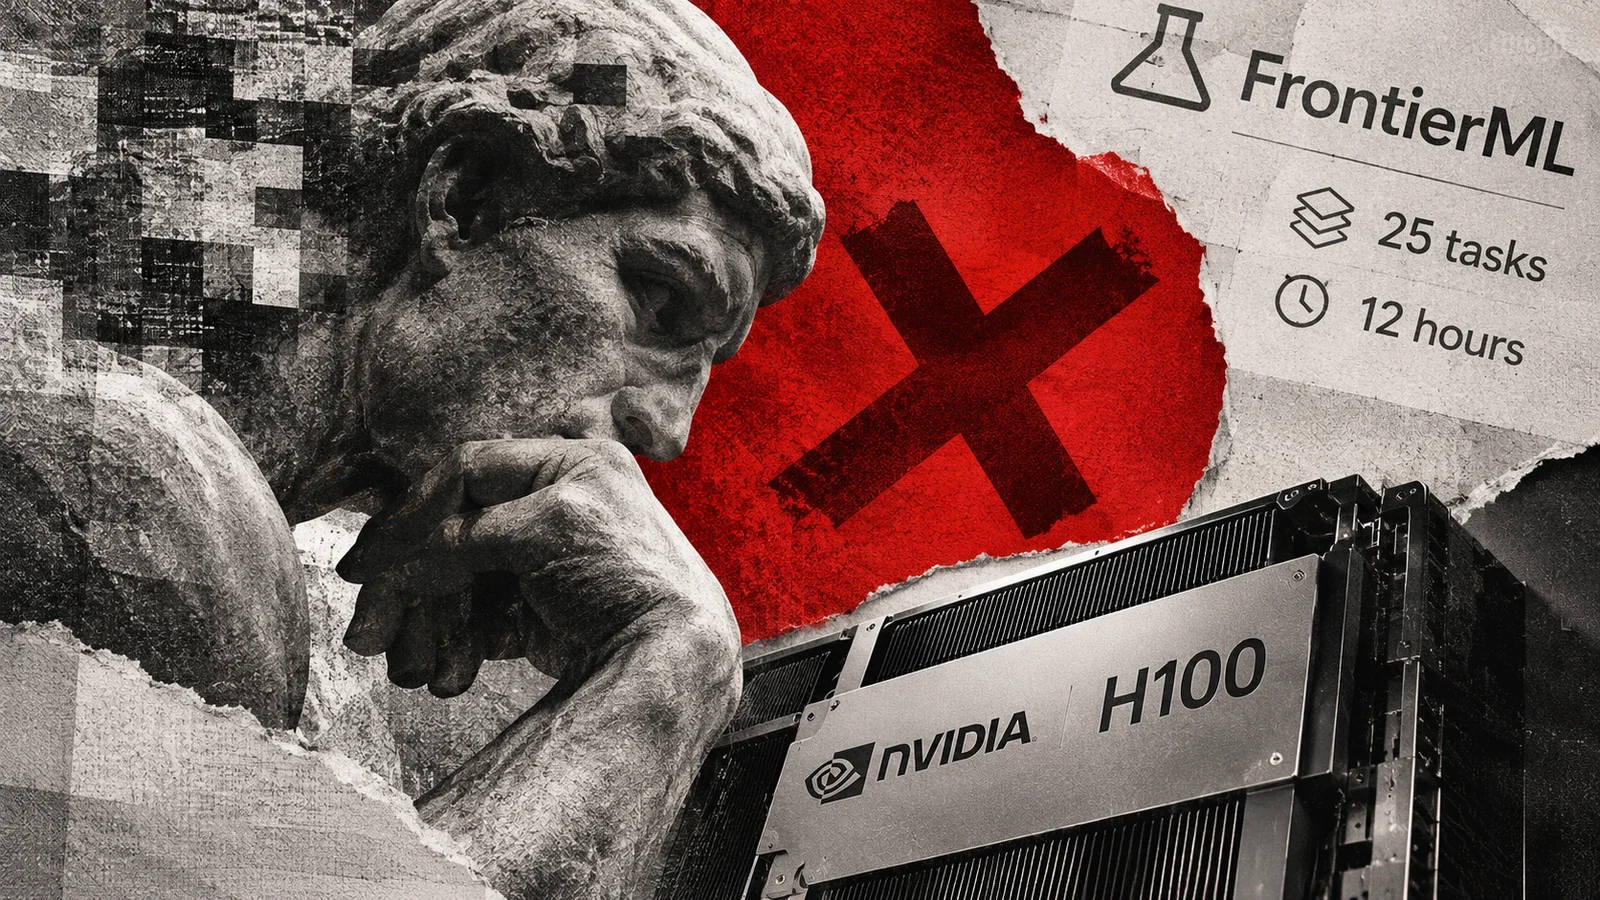
None of the five advanced artificial intelligence models evaluated in FrontierML managed to reach the high-performance level in any of the 25 machine learning research challenges. The benchmark was presented this Thursday (19) by Synthetic Sciences, a startup backed by Y Combinator.
The test evaluates the ability of AI agents to conduct experimental research autonomously, without direct access to the criteria used to determine the quality of the final results.
Each agent receives an open research problem and has 12 hours to work in Lab0, a virtual laboratory developed by the startup. The environment offers access to NVIDIA H100 GPUs, tools for generating synthetic data, and collections of scientific papers and datasets from arXiv and Hugging Face.
Unlike conventional evaluations, FrontierML requires agents to develop their own progress metrics, conduct experiments and determine to what extent the results obtained are reliable. At the end, the model or method developed is submitted to a reserved evaluation.
Among the five models evaluated, Anthropic's Claude Fable 5.2 showed the best performance, with a normalized average score of 0.523, followed by Claude Opus 5.5 and OpenAI's GPT-6 Astra.
The challenges include research on reinforcement learning, self-distillation and pre-training of language models without backpropagation, a technique widely used in training neural networks.
According to Synthetic Sciences, a fundamental part of empirical research consists precisely in determining how to measure the progress of an experiment and how much to trust those measurements. The startup announced the public release of 15 of the 25 challenges, accompanied by the complete records of the agents' activities.