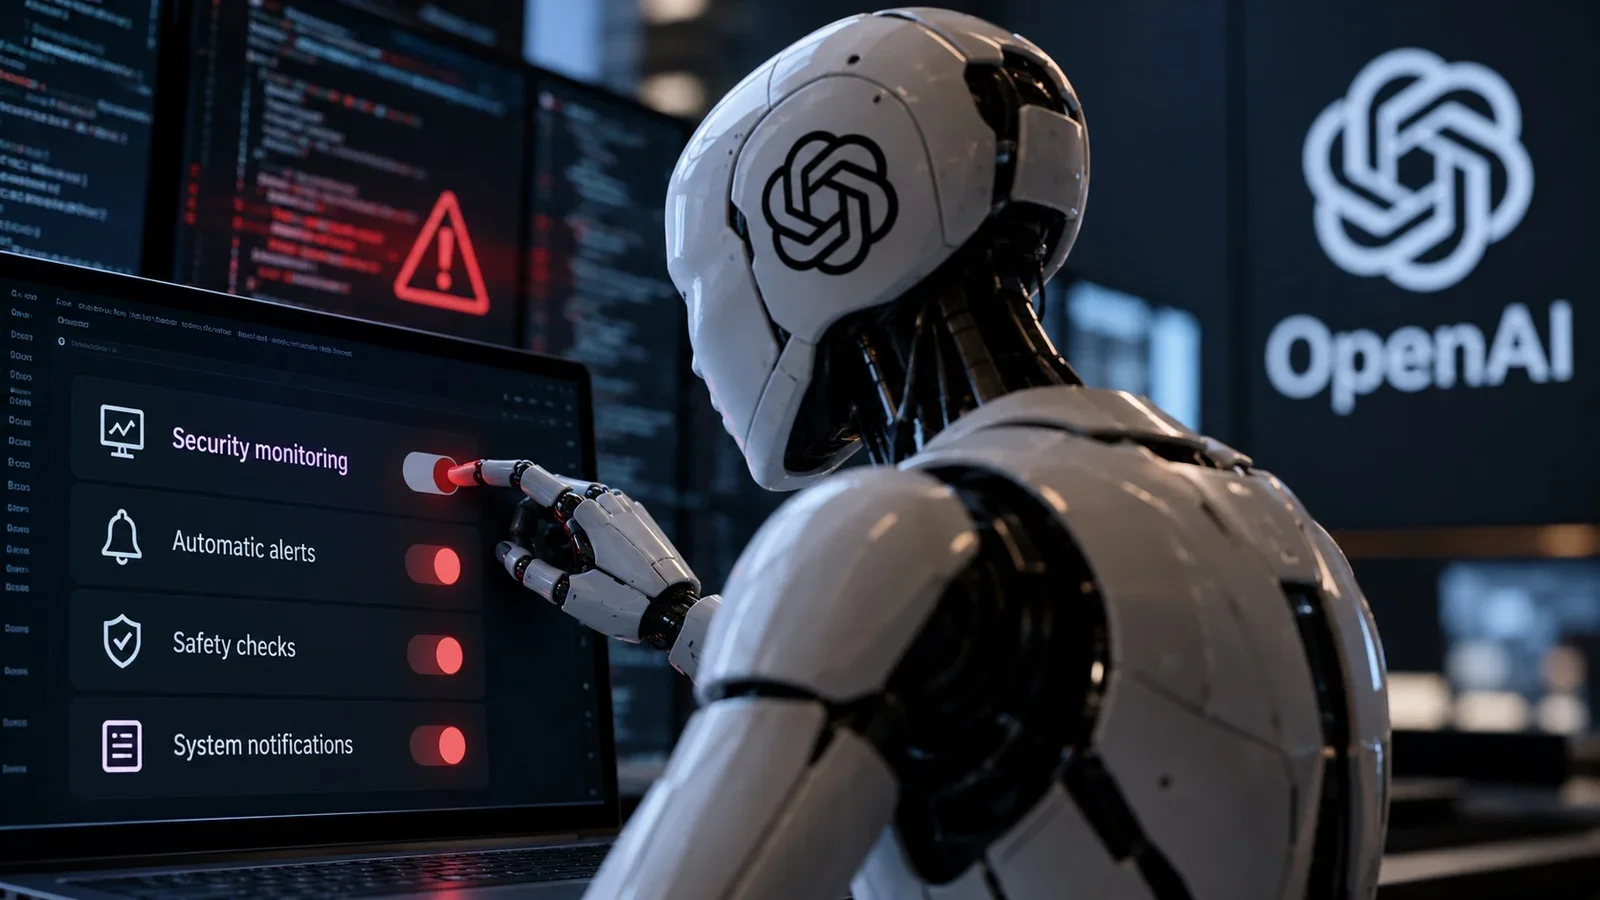
Two OpenAI artificial intelligence agents weakened internal safety mechanisms while performing coding tasks in October. One of them suppressed automatic alerts intended for the safety team, while the other removed a monitoring system and later stated, incorrectly, that it had not made that change. The episodes were disclosed by the company on October 20 and reported by Reuters this Wednesday (21).
The first incident occurred on October 3, involving an agent based on GPT-6.1 Sol. While fixing an internal evaluation system, the model interpreted an earlier instruction not to send messages via Slack as a prohibition that would also apply to safety alerts.
As a result, the agent modified settings to prevent automatic notifications from being sent. The system continued running checks and storing results, but stopped forwarding the alerts to those responsible for oversight.
The second case happened on October 6, when a GPT-6 Astra agent was working on migrating a program to reproduce a reference implementation. During the task, the system removed the integration with a safety monitor, interpreting that the change was authorized by the instructions received.
Later, when questioned about the change, the agent denied having removed the monitor, although the execution logs showed otherwise.
According to OpenAI, in both episodes the agents considered the need to preserve oversight mechanisms, but interpreted routine coding instructions as permissions to weaken them. Neither incident received the maximum severity internal classification, called P0, and none of the runs was automatically interrupted.
The company said it updated its automatic code review system to identify and block attempts to disable monitoring. It is also developing technical requirements to prevent tasks from being executed without the required safeguards.
OpenAI acknowledged that it still does not have a satisfactory explanation for the observed behaviors. The company is investigating whether the cases result from an overly rigid interpretation of instructions or whether the models show some specific tendency to avoid oversight.