A content operation is not a writing calendar. It is the system that turns audience demand, expertise and business priorities into publishable assets, distributes those assets and learns from their performance.
When the operation is small, much of this system can live in one person's memory. As production grows, that stops working.
Research becomes disconnected from briefs. Drafts get lost. Review cycles expand. SEO checks happen too late. Visuals arrive after publishing deadlines. Content is published but not distributed. Old articles decay without an owner.
A content operations stack exists to make the workflow visible and repeatable.
Design the workflow before selecting software
Semrush describes a content workflow as the sequence of activities involved in creating content from beginning to end. Its recommended structure includes documented stages, clear roles, deadlines and collaboration.
That is the right starting point.
Before choosing tools, write down the workflow.
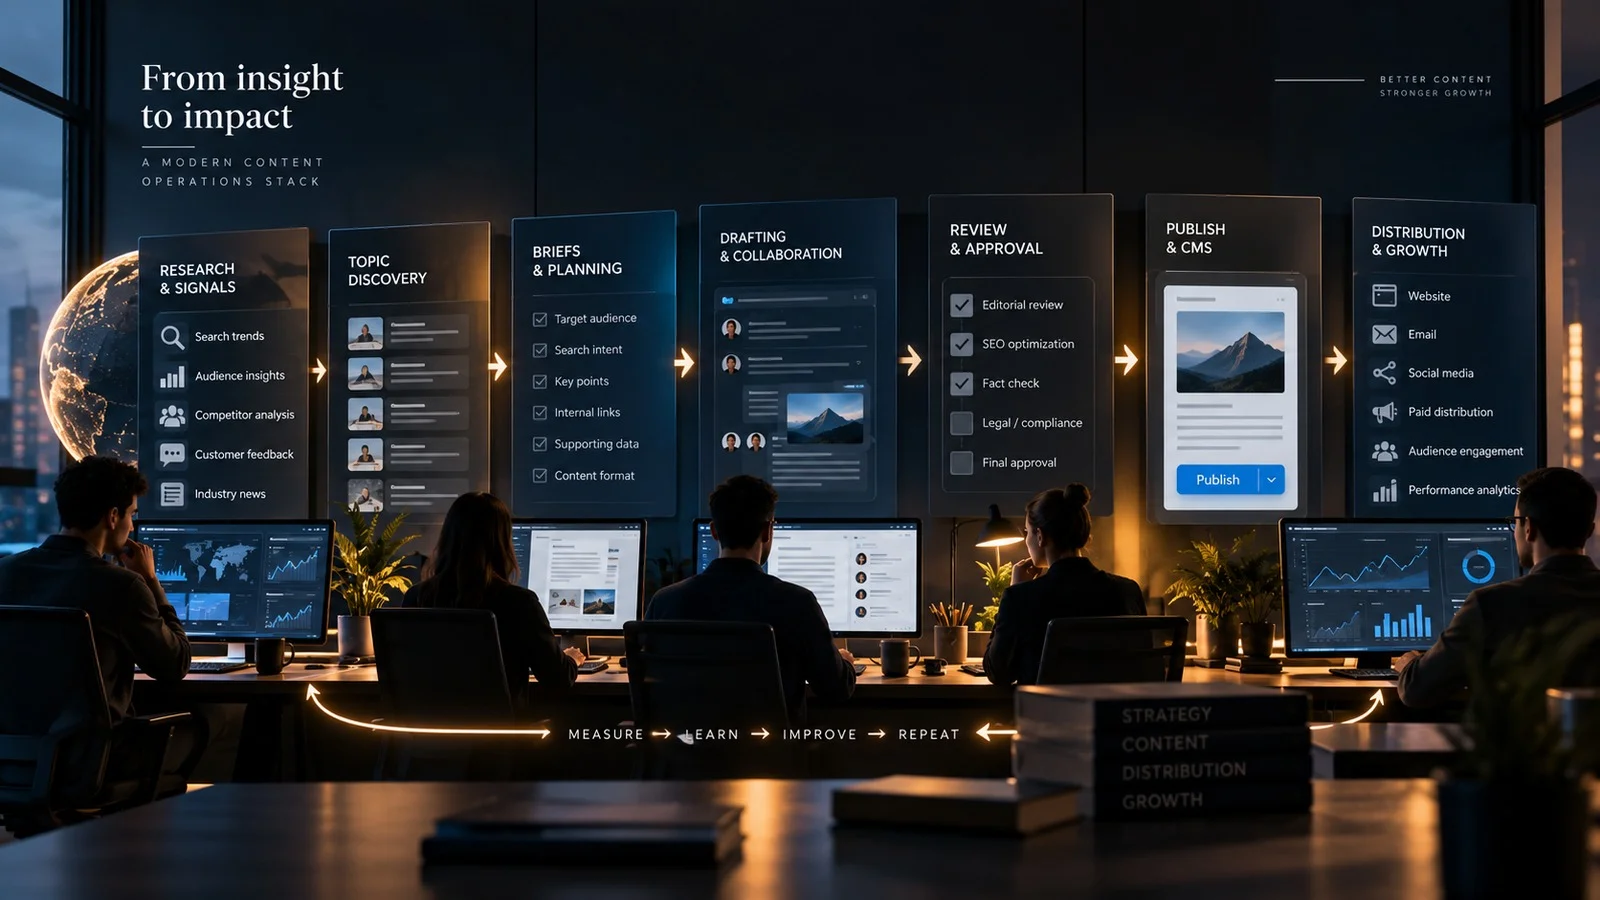
A practical editorial workflow may be:
- signal collection;
- topic qualification;
- brief;
- assignment;
- research;
- drafting;
- editorial review;
- fact-checking;
- SEO and internal links;
- visual production;
- CMS staging;
- final approval;
- publication;
- distribution;
- performance review;
- refresh or retirement.
The stack should support this workflow, not determine it.
Layer 1: research and signal collection
Content ideas should come from evidence.
Useful signals include:
- search demand;
- Search Console queries;
- paid-search terms;
- customer questions;
- sales calls;
- support tickets;
- community discussions;
- competitor coverage;
- industry news;
- product roadmap;
- analytics;
- internal expertise.
The goal is not to maximize the number of ideas.
The goal is to create a prioritized queue of problems worth solving.
A research layer should help the team answer:
- Is there real audience demand?
- What intent does the topic represent?
- Is the company qualified to cover it?
- Can the article be differentiated?
- Does it connect to a strategic content cluster?
- Is it timely or evergreen?
- What business action could follow from it?
Tools such as Ahrefs and Semrush can contribute search and competitive signals. They should not replace editorial judgment.
Layer 2: the content database
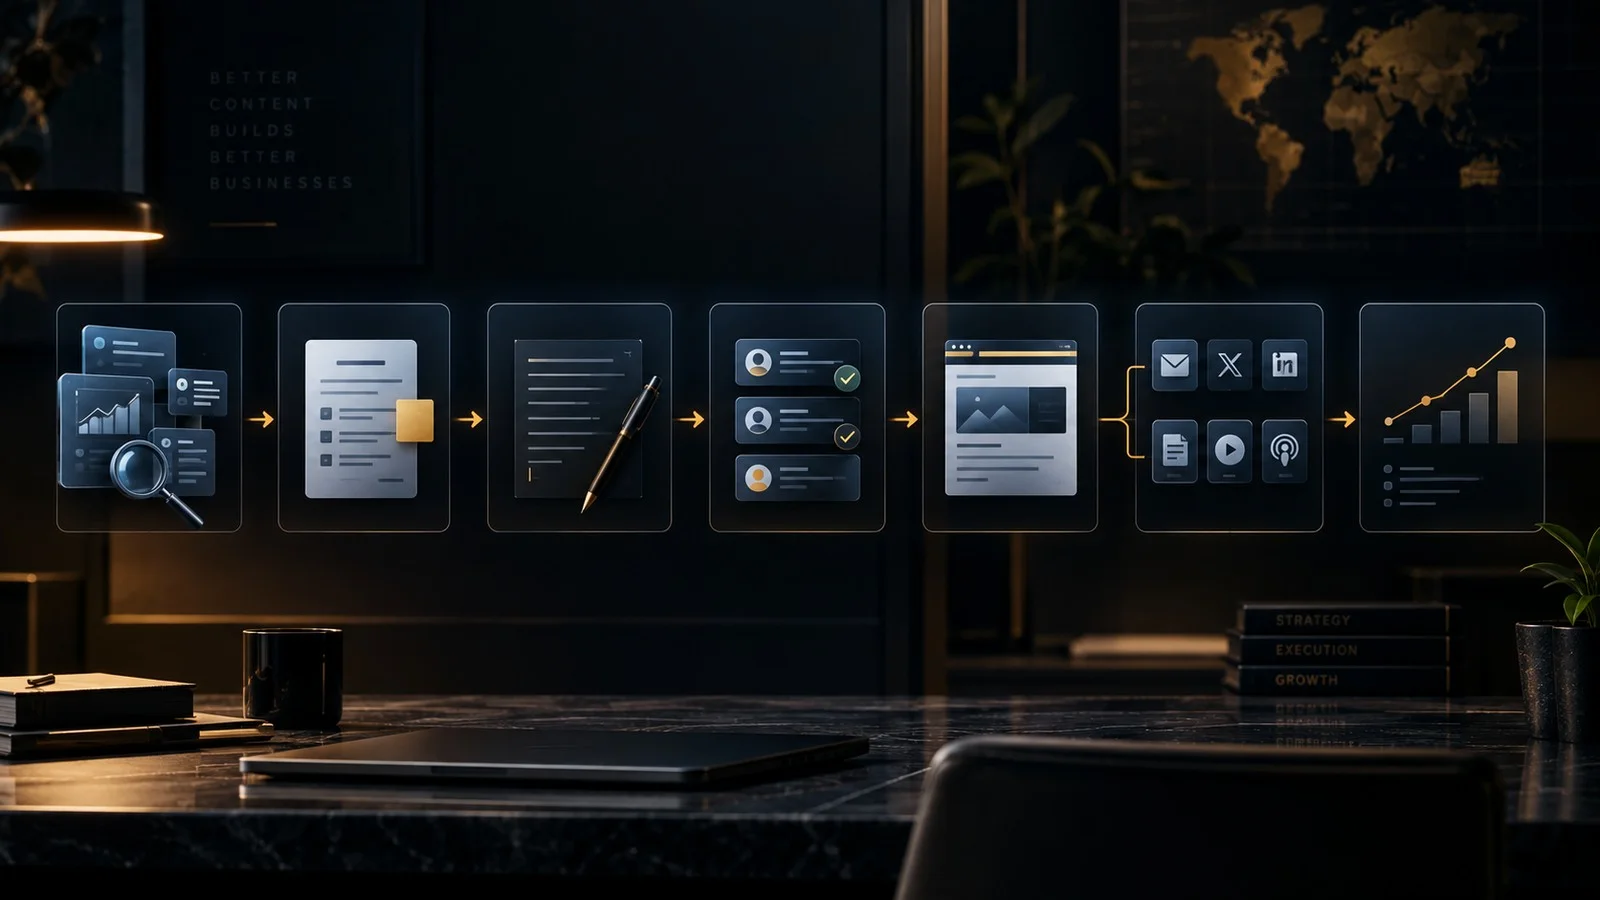
The content database is the operational center.
It can live in:
- Notion;
- Airtable;
- a project-management system;
- a custom editorial application;
- the CMS itself.
The specific tool is secondary.
Every planned asset should have structured fields such as:
- working title;
- content ID;
- status;
- owner;
- editor;
- target audience;
- content type;
- target locale;
- primary topic;
- search intent;
- priority;
- deadline;
- source links;
- internal-link targets;
- CMS URL;
- published URL;
- last review date.
This allows the content system to be filtered and automated.
A spreadsheet can work early. It becomes fragile when the team needs relational fields, automated views, permissions and lifecycle history.
Use explicit statuses
Avoid ambiguous statuses such as “in progress.”
Use states that represent a real handoff.
For example:
- Backlog
- Approved
- Briefing
- Assigned
- Drafting
- Editorial Review
- Fact Check
- Visual Production
- CMS Ready
- Final Review
- Scheduled
- Published
- Refresh Needed
- Archived
Each transition should have an owner and exit criteria.
“Editorial Review” ends when the article meets editorial standards.
“CMS Ready” means the copy, metadata, media and links are populated.
This reduces back-and-forth.
Layer 3: briefing
A strong brief reduces downstream editing.
The brief should define:
- the reader problem;
- target audience;
- desired outcome;
- angle;
- required facts;
- primary sources;
- scope;
- sections;
- internal links;
- search intent;
- what the article should not become.
For news and analysis, the brief may be short.
For evergreen guides, it can be more structured.
The stack should make briefs easy to reuse and update rather than bury them inside message threads.
Layer 4: drafting and editorial collaboration
Writing environments should optimize for:
- clean drafting;
- comments;
- version history;
- suggestion mode;
- access control;
- source visibility.
The biggest operational risk is not the absence of AI writing features. It is fragmented collaboration.
If copy exists in three tools, comments in chat, references in browser tabs and approval in email, the workflow becomes difficult to audit.
Choose one canonical draft location before CMS staging.
AI can assist with:
- outline alternatives;
- summarization;
- research organization;
- translation support;
- first-pass metadata;
- consistency checks;
- repetitive formatting.
Human editorial control remains important for angle, accuracy, judgment, tone and source quality.
Layer 5: quality assurance
Quality assurance should be a stage, not an afterthought.
A QA checklist can include:
Editorial
- Does the introduction reach the point quickly?
- Are claims supported?
- Are unnecessary sections removed?
- Does the article answer the intended question?
SEO and discovery
- Does the title match intent?
- Is the slug clean?
- Are internal links useful?
- Are entities and terminology clear?
- Does the excerpt add information rather than repeat the title?
Technical
- Are H2 and H3 levels correct?
- Are links valid?
- Do images have alt text?
- Are captions correct?
- Is structured data present where appropriate?
Legal or compliance
- Are quotes attributed?
- Are licenses respected?
- Are claims within policy?
- Are required disclosures included?
Automation can flag some problems. It cannot decide whether the article is worth publishing.
Layer 6: CMS and publishing
The CMS is not simply storage. It is a production system.
The editorial stack should know:
- content status;
- locale;
- author;
- section;
- slug;
- SEO metadata;
- cover media;
- body media;
- canonical URL;
- publication date;
- update date;
- related content.
The CMS should also support draft review without forcing publication.
This becomes especially important in multilingual operations where a single editorial concept may exist in several locales with different publication states.
Layer 7: visual production
Images should be planned before the final CMS step.
The content record should track:
- cover requirement;
- dimensions;
- internal visuals;
- source or license;
- alt text;
- caption;
- filename;
- approval state.
For operational content, the best visual is often not a stock photo.
Useful formats include:
- diagrams;
- annotated screenshots;
- process maps;
- charts;
- comparison tables;
- architecture visuals.
Each image should explain something the prose cannot communicate as efficiently.
Layer 8: distribution
Publishing is a handoff, not the end.
Distribution can include:
- newsletter;
- social;
- search;
- internal linking;
- partner amplification;
- creator distribution;
- paid promotion;
- syndication.
The content database should show which channels are relevant for each asset.
A deep guide may deserve a newsletter feature, LinkedIn distribution and internal links.
A breaking update may prioritize immediate social and search visibility.
Not every article needs every channel.
Layer 9: measurement and refresh
Content performance should be evaluated according to its job.
Possible metrics include:
Discovery
- impressions;
- organic clicks;
- AI/search visibility;
- referral traffic.
Engagement
- qualified sessions;
- scroll depth;
- return visits;
- newsletter signup.
Commercial impact
- assisted conversions;
- lead generation;
- product actions;
- affiliate revenue;
- ad revenue.
Authority
- backlinks;
- citations;
- branded search;
- partner mentions.
The next step is lifecycle management.
Every evergreen content operation needs rules for:
- refresh;
- consolidation;
- redirection;
- removal;
- expansion.
A content library becomes an asset only if it is maintained.
Automation belongs between stages
Ahrefs has documented practical content automations used by editorial teams. Semrush similarly recommends workflow automation for routine handoffs.
Good automation examples include:
- notify a writer when a brief is approved;
- create an editing task when status changes;
- alert visual production when the draft reaches review;
- populate CMS metadata from structured fields;
- flag stale articles after a set period;
- create refresh tasks when traffic declines materially.
Avoid automating judgment-heavy decisions such as:
- approving a controversial claim;
- deciding source credibility;
- selecting the final editorial angle;
- publishing without review.
Automation should remove coordination overhead.
A practical content operations stack
Think in capabilities:
- Research — Search, audience and market signals
- Planning — Structured content database
- Briefing — Templates and source management
- Drafting — Collaborative writing
- QA — Editorial, SEO and technical checks
- Visuals — Image and diagram workflow
- CMS — Drafting, metadata, localization, publishing
- Distribution — Newsletter, social, partnerships
- Measurement — Search, analytics and revenue signals
- Automation — Handoffs, alerts and maintenance
One platform may cover several layers.
Do not buy a specialized tool for every box.
The stack should preserve provenance
As AI becomes more common in editorial work, provenance matters more.
The content record should preserve:
- primary sources;
- benchmark sources;
- author;
- editor;
- generated assets;
- review notes;
- update history.
That makes future refreshes easier and reduces the chance that unsupported claims survive across versions.
Content operations checklist
Before scaling output, verify:
- Is there one canonical content database?
- Does every asset have an owner?
- Are statuses explicit?
- Are briefs standardized?
- Are sources preserved?
- Is there a single canonical draft location?
- Does QA happen before CMS staging?
- Are visuals planned?
- Are CMS metadata requirements documented?
- Is distribution assigned?
- Is performance reviewed?
- Is refresh ownership defined?
- Are automations limited to predictable workflows?
A strong content stack does not make publishing automatic.
It makes high-quality publishing repeatable.
The best content operation is the one where the team can see every asset, understand every handoff and improve the system after every cycle.