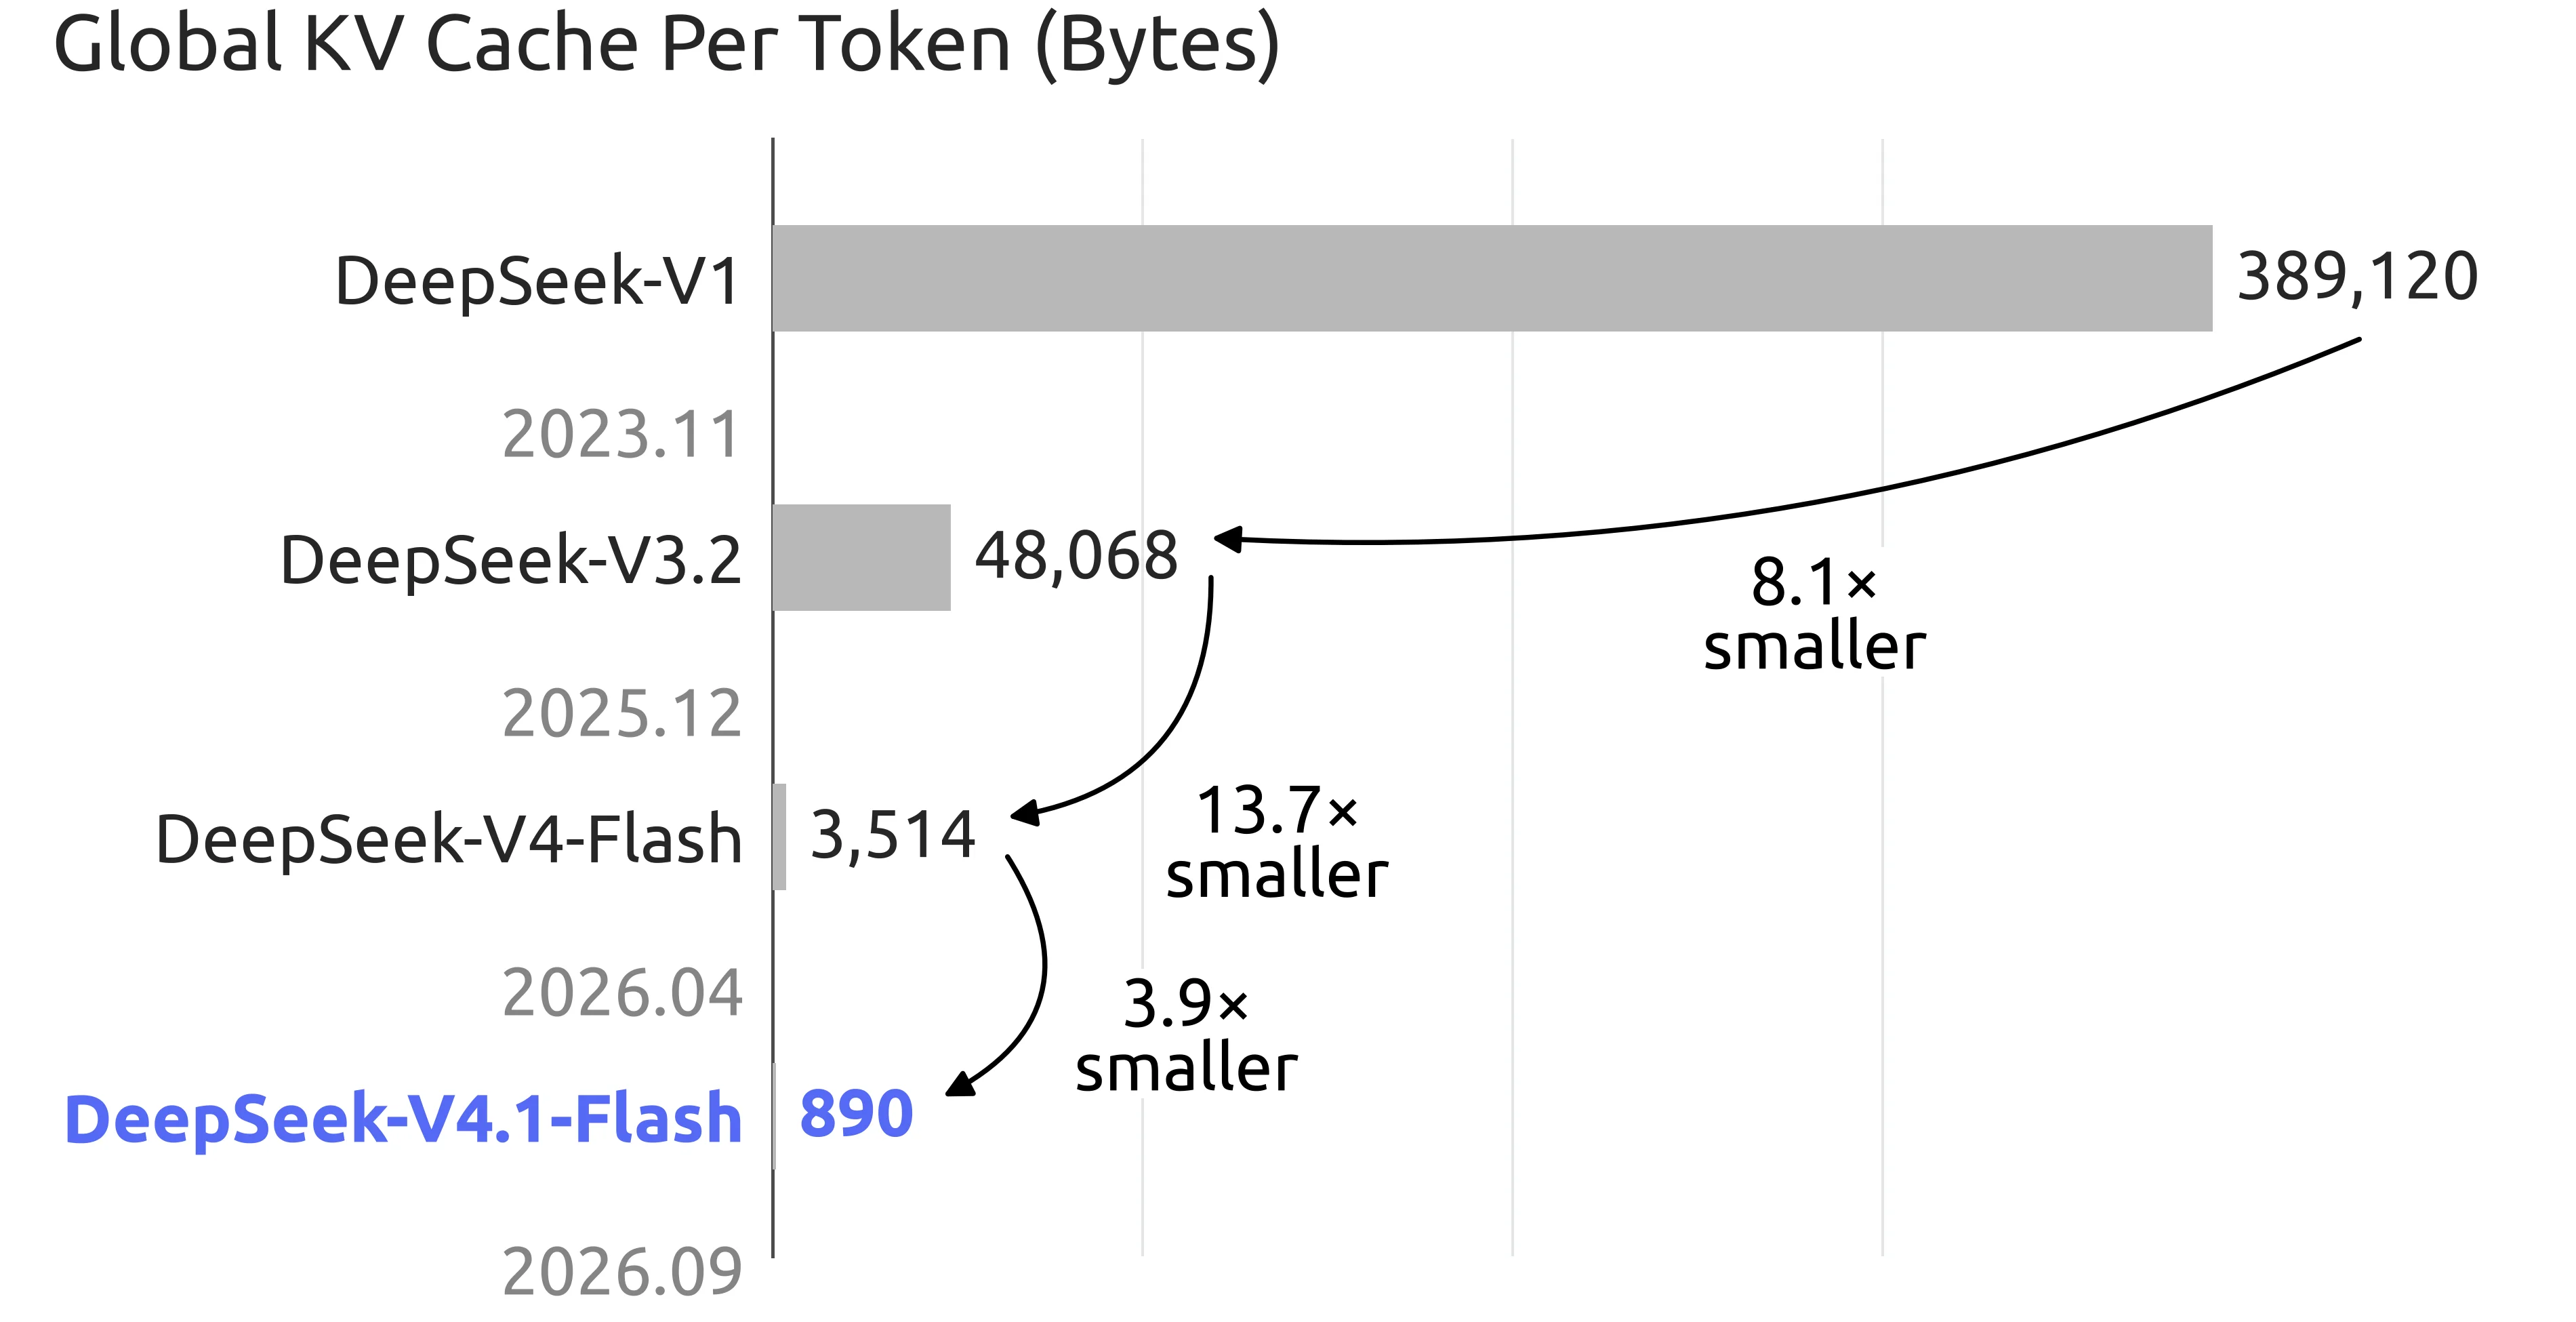
DeepSeek announced the V4.1-Flash, the first model of a new architecture from the company, with performance above V4-Pro in different benchmarks and a significant reduction in memory consumption. The new model requires about one quarter of the HBM and one eighth of the SSD storage used by the previous generation's KV cache.
V4.1-Flash uses a Mixture-of-Experts (MoE) architecture with 552 billion parameters, but activates only 8 billion in input processing and 16 billion during response generation. The proposal is to reduce computational cost without compromising performance.
The model also brings native multimodal vision and support for contexts of up to 1 million tokens. According to DeepSeek, changes in pre-training and post-training allowed Flash to outperform V4-Pro in different evaluations.
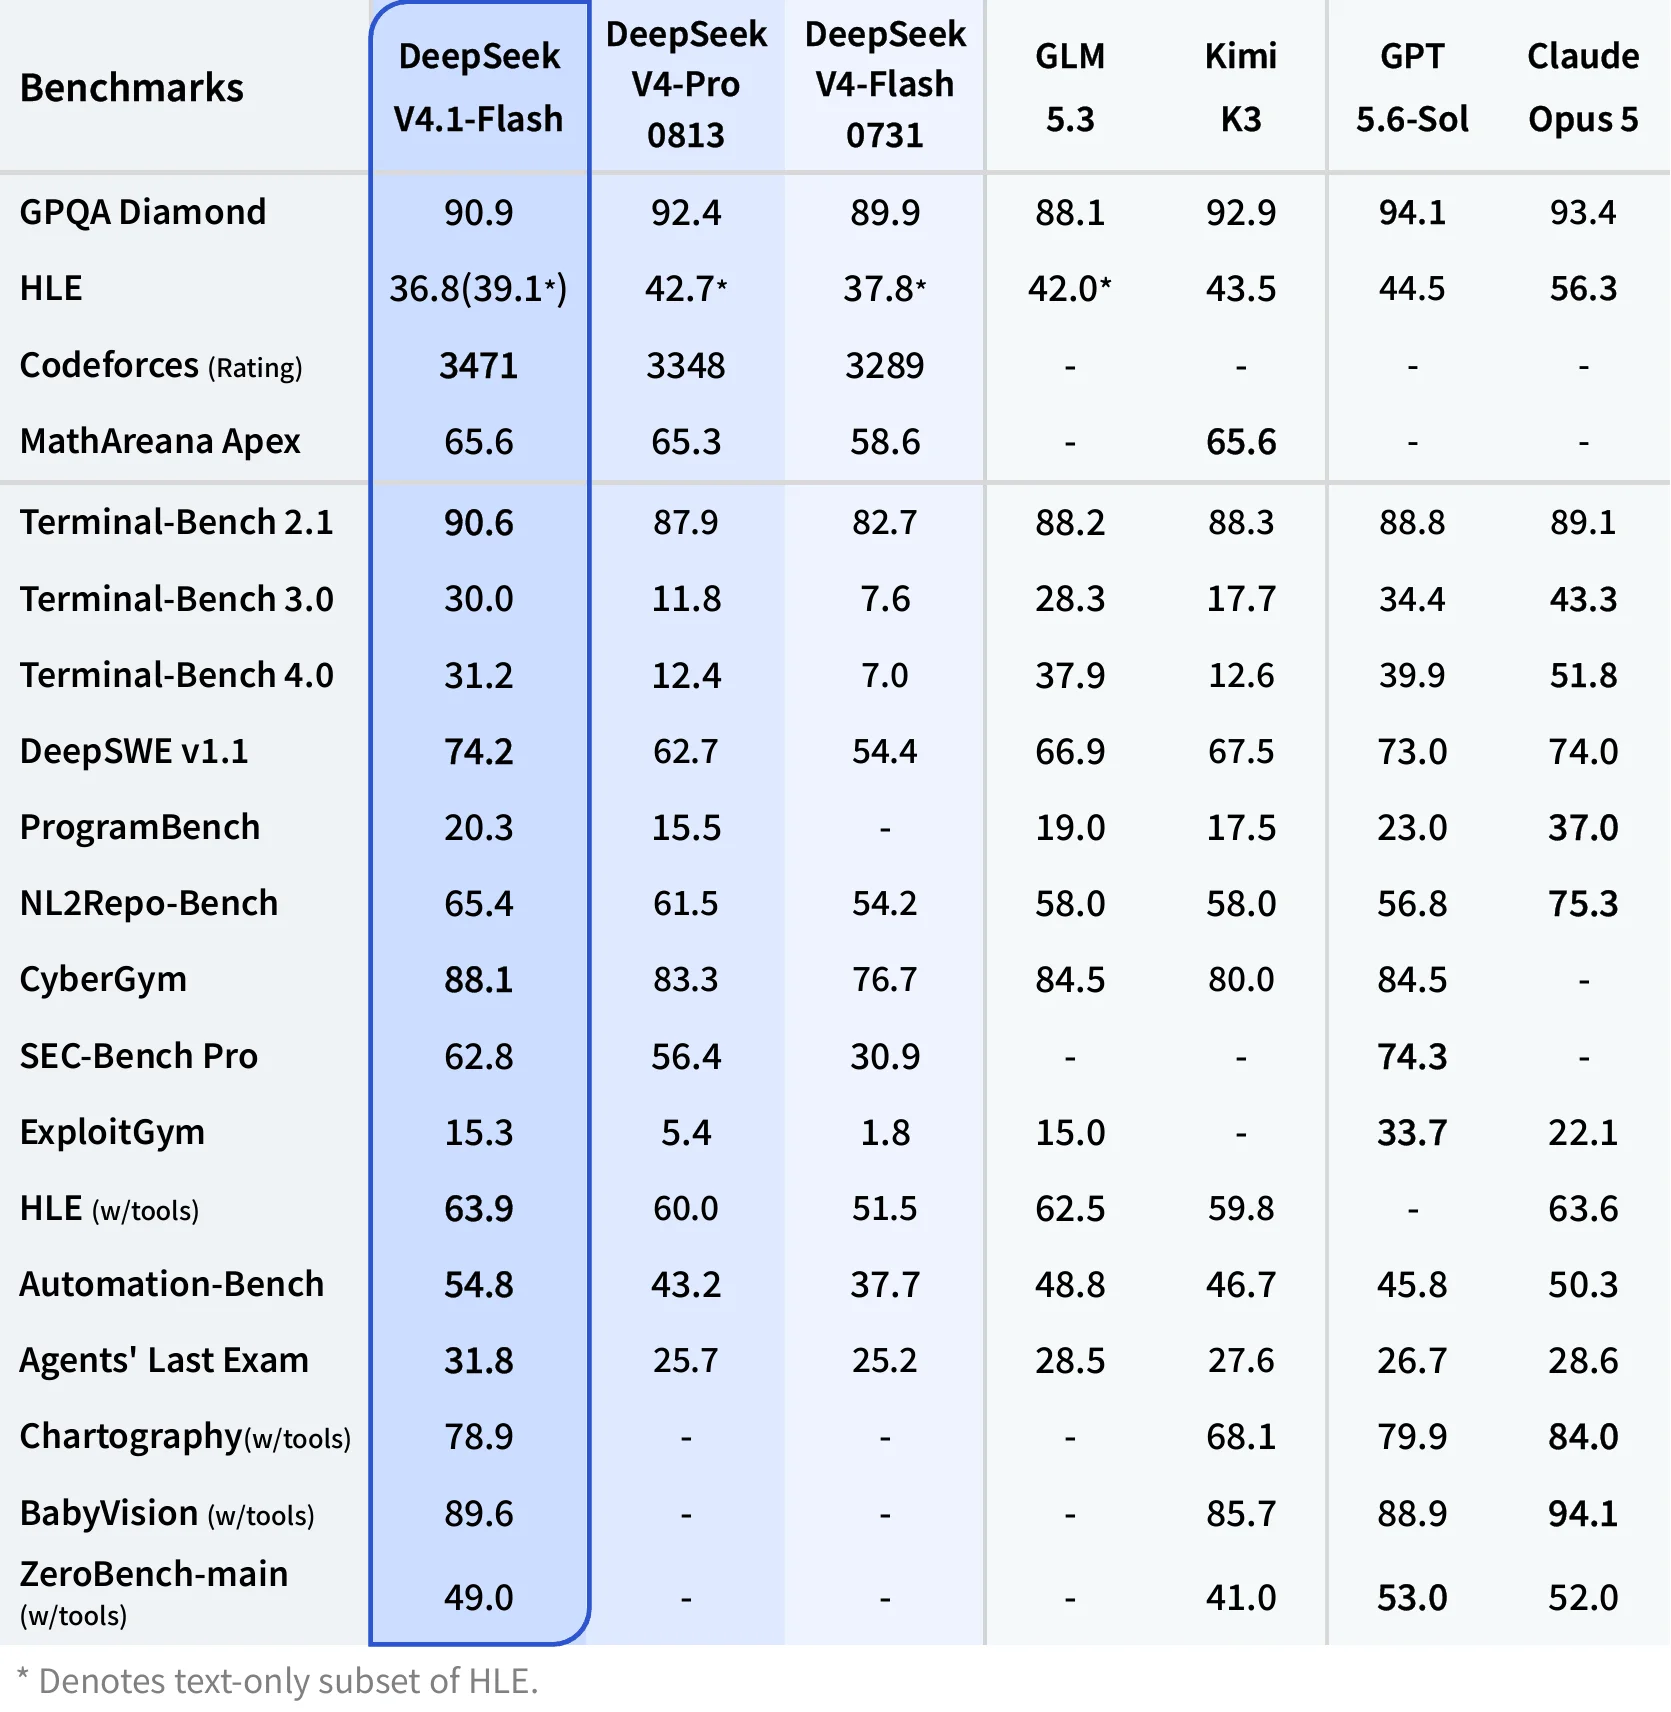
Flash will temporarily replace V4-Pro
Starting September 14, requests sent to the deepseek-v4-pro identifier will be directed to V4.1-Flash. The redirection will continue until the launch of the future V4.1-Pro.
The decision temporarily places the new Flash in the place of the company's Pro model, even though it belongs to a line aimed at greater efficiency.
The new architecture also reduces the amount of memory needed to maintain the KV cache, a structure used to store context during inference. This gain is especially relevant in workloads with large volumes of tokens.
DeepSeek also reduced API prices. V4.1-Flash is already available under the deepseek-flash identifier, and the model weights were released for use outside the company's infrastructure.


